Loading Howl Media Labs
Preparing the page and animations...
Loading Howl Media Labs
Preparing the page and animations...
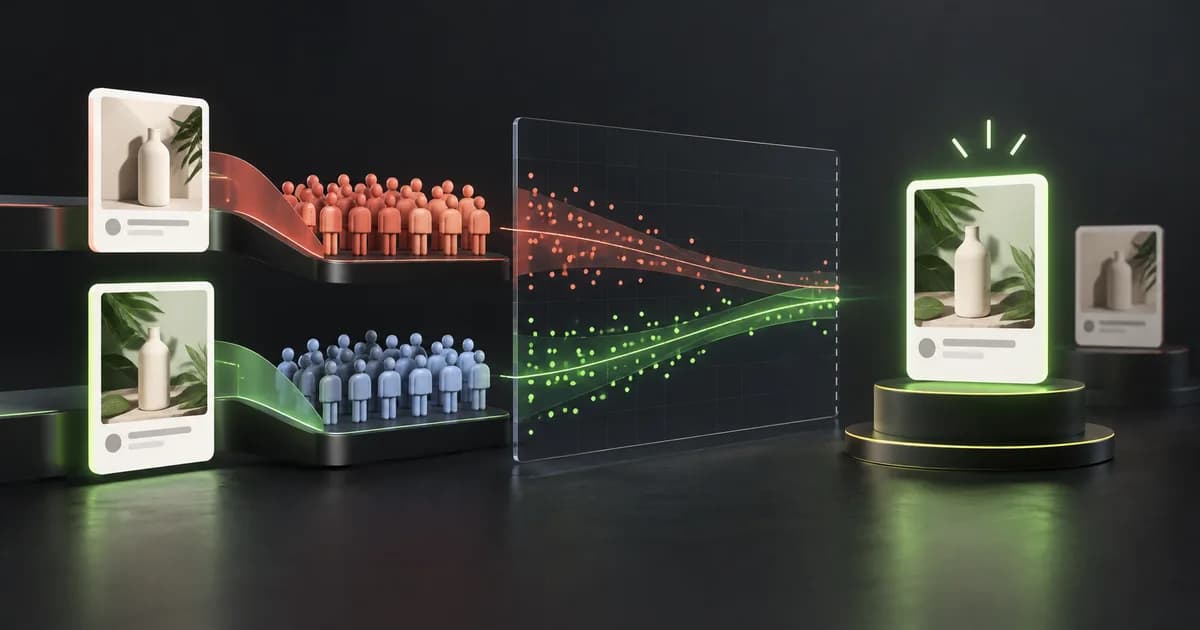
To size a creative test, start with baseline conversion rate, the smallest lift worth acting on, confidence and power. At a 2% baseline, detecting a 20% relative lift to 2.4% needs roughly 21,109 observations per arm at 95% confidence and 80% power. If volume cannot support that, test a larger change or use a higher-frequency upstream metric.
Creative teams often declare a winner after a few days because one ad has a lower CPA or higher CTR. That comparison may be useful for pacing, but it is not automatically a valid experiment. When the difference is small and the sample is thin, the apparent winner can reverse as more users and conversions arrive.
A sample-size plan answers a practical question before the campaign starts: how much evidence is needed to detect a difference large enough to change the business decision?
Without that plan, teams tend to:
Google's experiments documentation supports controlled comparisons across several campaign types. It recommends allowing undecided tests to gather more data and notes that some experiment types may need four to six weeks. Meta's Reels advertising guidance likewise recommends A/B testing creative approaches rather than treating format recommendations as guaranteed account results.
4.5x Total ROI
See how a bespoke tailoring brand hit 4.5x total ROI across channelsRead it →
Four inputs drive the planning estimate:
| Input | Meaning | Planning mistake to avoid | | --- | --- | --- | | Baseline rate | Current conversion rate for the chosen outcome | Using a blended account rate from a different audience or funnel | | Minimum detectable effect | Smallest lift worth acting on | Asking the test to detect any difference, however commercially trivial | | Significance level | Tolerance for a false positive | Lowering the threshold after seeing weak results | | Statistical power | Probability of detecting the planned effect if it exists | Ignoring false negatives in low-volume accounts |
This guide uses a two-sided 5% significance level and 80% power for planning. That convention is not a rule imposed by Meta or Google. It is a disclosed choice that makes the worked examples comparable.
Use the Conversion Rate Calculator to establish the baseline with the same numerator and denominator you will use in the experiment. The conversion-rate glossary explains why changing either definition invalidates a comparison.
For a binary outcome such as purchase or qualified lead, an approximate two-proportion calculation shows how quickly the requirement grows when the baseline is low or the desired lift is small.
| Baseline | Target | Relative lift | Approx. observations per arm | Approx. total | | ---: | ---: | ---: | ---: | ---: | | 1.0% | 1.2% | 20% | 42,693 | 85,386 | | 2.0% | 2.2% | 10% | 80,682 | 161,364 | | 2.0% | 2.4% | 20% | 21,109 | 42,218 | | 2.0% | 2.6% | 30% | 9,798 | 19,596 | | 5.0% | 6.0% | 20% | 8,158 | 16,316 |
Method: estimates use the normal approximation for two independent proportions with equal allocation, a two-sided 5% significance level and 80% power. They assume independent observations and a stable binary outcome. They are planning estimates, not replacements for native platform analysis.
The table exposes the real constraint for many Indian D2C accounts: detecting a 10% relative improvement in purchase rate may require far more traffic than the available weekly budget can buy. The answer is not to stop early. Choose a more material creative change, a longer test, a higher-frequency outcome or a directional learning objective with appropriately cautious language.
Google's statistical methodology says its experiments use bucketed data, jackknife resampling and two-tailed testing. Eligible auctions are assigned to control and treatment before targeting, and the interface can report a confidence interval around the estimated difference.
The experiment scorecard guide lists common reasons for a non-significant result:
The native scorecard is the operational source of truth for a Google Ads experiment. The sample-size table above is a preflight estimate that helps decide whether the test is feasible before budget is committed.
Test one material hypothesis while keeping the rest of the system as stable as practical.
For example:
Do not change the hook, audience, landing page, offer and optimization event in the same two-cell test. Even if the treatment wins, the team will not know what caused the difference.
Google advises that an A/A test should keep the original and experiment identical, including changes and approvals. Its experiment FAQ also warns that simultaneous experiments can interfere with one another and recommends sequential testing where overlap would contaminate results.
HML's creative-fatigue guide explains when to refresh assets after launch. The short-form video strategy helps turn the winning hypothesis into platform-native variants without assuming that every resize is a new idea.
Consider a fictional home-care brand with a stable 2% purchase rate. The team wants to compare a demonstration-led video against its current testimonial-led creative. A 20% relative lift—to 2.4%—is the smallest improvement that would justify new production and a wider rollout.
| Planning field | Decision | | --- | --- | | Primary metric | Net purchase conversion rate | | Baseline | 2.0% | | Minimum detectable effect | +20% relative, or +0.4 percentage points | | Confidence and power | 95% two-sided; 80% power | | Planned sample | 21,109 eligible observations per arm | | Expected purchases at baseline | About 422 per arm | | Allocation | 50:50 | | Minimum calendar coverage | Two full weekly cycles plus conversion lag | | Guardrails | Refund rate, contribution per visitor and new-customer mix |
Suppose each arm reaches the planned observation count. Control converts at 2.02% and treatment at 2.37%. The treatment is commercially promising, but the team should still use the platform confidence interval and backend transaction reconciliation before applying it. If refund rate or contribution worsens, a purchase-rate win may not be a profit win.
Disclosure: all figures are synthetic. No client result or universal benchmark is implied.
Use one of five honest alternatives:
Do not solve low power by checking more often, adding variants mid-test or switching the success metric after results appear.
Use a three-part decision gate:
| Gate | Evidence | | --- | --- | | Statistical | Platform experiment status, interval and planned primary metric | | Commercial | Net orders, contribution, refunds and new-customer economics | | Operational | Creative can be produced, refreshed and served without policy or brand risk |
The performance marketing furniture case study shows why account structure and commercial outcomes need to be read together; its results are not evidence for the synthetic test above.
If the team is running many variants but cannot explain the hypothesis, stopping rule or minimum sample, request a creative experimentation audit from HML's performance marketing team. The deliverable should be a ranked test backlog, feasibility estimate and decision register—not a weekly spreadsheet of premature winners.
Reviewed by rajkumar-tahalani on 24 September 2026. Access dates are shown for time-sensitive references.
Performance Marketing
Google Ads Data Strength Uplift: A Measurement Audit for Indian D2C Brands
Performance Marketing
Google Ads Target Bidding Update: Audit Limited-by-Budget Campaigns
Free Tool
CPM & CPC Calculator
Work out CPM, CPC, and CTR from your campaign data.
Case Study
4.5x Total ROI
How a Premium Bespoke Tailoring Brand Achieved 4.5x ROI Across Digital Channels
We help Indian D2C brands grow with performance marketing, AI automation, and AEO-ready content. Book a free strategy call and we'll show you where the biggest wins are.
Or See how a bespoke tailoring brand hit 4.5x total ROI across channels.