Loading Howl Media Labs
Preparing the page and animations...
Loading Howl Media Labs
Preparing the page and animations...
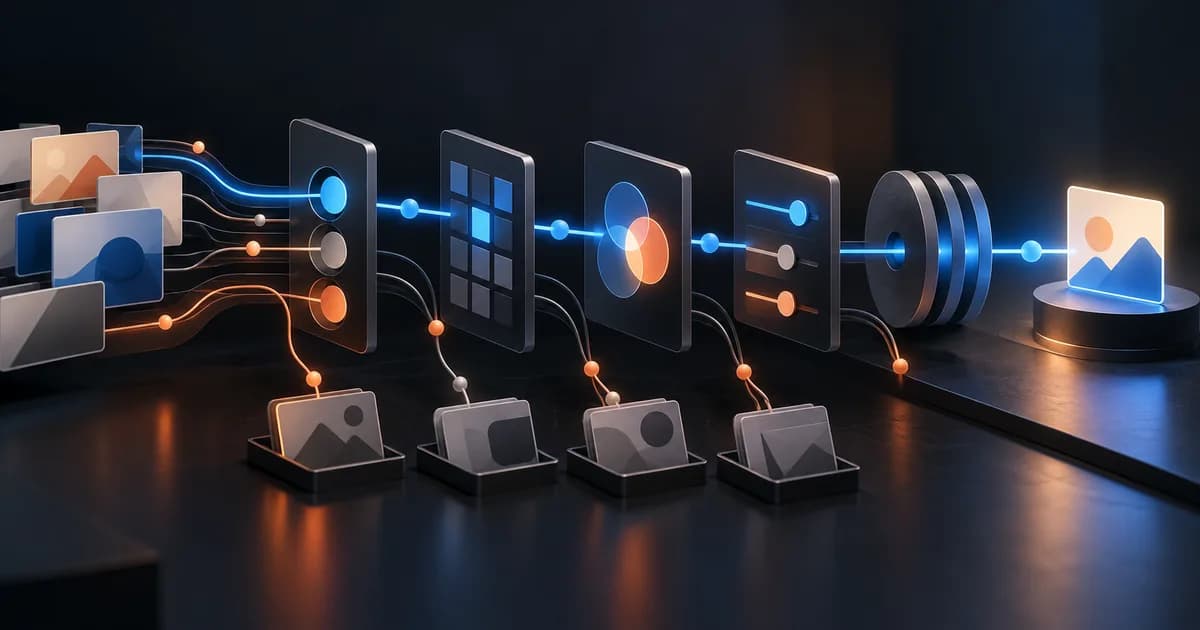
When ChatGPT Ads do not deliver, check hard blockers before changing bids or creative: account verification, billing, dates, review status, policy, budget allowance and product eligibility. If those pass, diagnose conversational relevance, auction admission, pacing and final placement suitability. Zero impressions do not prove one cause, and an active status does not guarantee delivery.
OpenAI's 21 October 2026 engineering explanation describes a delivery system built for evolving conversational goals rather than isolated search queries. That makes “no impressions” a multi-stage diagnostic problem. An ad can be valid yet never become relevant enough for retrieval, competitive enough for auction admission or appropriate enough for the final conversation.
This guide focuses on delivery diagnosis. HML's ChatGPT Ads launch guide covers the broader channel and measurement setup; the ChatGPT shopping product-visibility audit covers organic product discovery rather than paid delivery.
OpenAI's ad-stack article describes a stateful ads session and an LLM-based orchestrator that can call retrieval, ranking, relevance and auction tools. OpenAI says the ad system is separate from answer generation so ads do not influence ChatGPT's response.
For an advertiser, the useful mental model is a sequence of gates:
| Gate | Question | Observable advertiser evidence |
|---|---|---|
| Account | Is the advertiser allowed and operational? | Verification, account status, billing status |
| Campaign | Is the campaign eligible now? | Active state, dates, schedule, allowance |
| Ad | Is the complete ad experience eligible? | Review status, creative, destination, product/feed state |
| Retrieval | Could the system consider the ad for this goal? | Coherent ad group, accurate offer and context hints |
| Relevance | Is the ad useful in the current conversational context? | Message-use-case fit and landing-page proof |
| Auction | Does the eligible candidate clear admission and ranking? | Bid strategy, budget, delivery and competitive evidence available in account |
| Placement | Is this a suitable moment and context for an ad? | Platform-controlled integrity and placement rules |
The first three gates can often produce an explicit status or error. The last four are probabilistic and platform-controlled. Do not invent a precise cause when the available evidence only proves non-delivery.
OpenAI's troubleshooting guidance says to confirm that the campaign and ads are active, review is complete and the current date is within the campaign window. It also calls out account verification, billing and remaining spending allowance.
Use this order:
OpenAI's billing documentation states that a failed payment can stop delivery. It also warns that resolving payment does not prove delivery has resumed because other blockers may remain.
That last distinction matters: a repaired prerequisite is not evidence that every downstream gate passed.
Yes. OpenAI's campaign guidance describes a daily budget as an average delivery target over a seven-day period. Daily spend can fluctuate, while the applicable weekly limit remains the stronger boundary. If a campaign uses the weekly allowance early, delivery can stop later in the week even when it is still active.
Before labeling a campaign “broken,” compare:
Use the Ad Budget Calculator to plan an evidence threshold from conversion and CAC assumptions, but treat its result as a planning envelope. It cannot diagnose platform pacing or guarantee spend.
OpenAI's Ads basics says matching can consider the conversation's context and intent, landing page, title, copy and advertiser-provided context hints. It describes a relevance-weighted second-price auction among eligible ads.
The context-hint guide is explicit: hints are not exact-match keywords and do not guarantee delivery. They should add one accurate, specific idea about the product, who it helps or when it is useful.
| Weak diagnostic response | Better response |
|---|---|
| Add a long list of keywords | Split genuinely different use cases into coherent ad groups |
| Make the hint broader | State one true product-to-need connection |
| Promise nationwide service | Match the actual service area and supported controls |
| Duplicate the headline | Add relevant information absent from the creative or page |
| Change every hint at once | Change one hypothesis and preserve a control where feasible |
A low-delivery ad for compact desks might mix renters, corporate offices, gaming rooms and school furniture in one group. Separating those needs can improve diagnostic clarity, but it still does not promise impressions.
Yes. Approval establishes that an ad can be eligible; it does not make every conversation suitable for advertising.
OpenAI's ad policies distinguish advertiser, creative and landing-page review from placement controls. The policies exclude ads from sensitive and brand-unsafe conversational contexts. OpenAI's engineering article also describes final eligibility checks after the auction for whether an ad feels appropriate in the specific chat.
Advertisers should therefore avoid reverse-engineering personal or sensitive conversations from aggregate non-delivery. The defensible action is to improve genuine offer relevance, comply with placement and content policies, and use the controls the platform exposes.
Consider a fictional Indian home-and-lifestyle advertiser reviewing six ad groups after launch. The data is synthetic.
| Ad group | Initial observation | First confirmed cause | Correct action |
|---|---|---|---|
| Storage furniture | 0 impressions, “Not serving” | Ad review incomplete | Wait for review; do not edit repeatedly |
| Desk accessories | 0 impressions after prior spend | Weekly allowance exhausted | Replan pacing for next budget week |
| Modular desks | 0 impressions and payment notice | Outstanding billing failure | Resolve invoice, then recheck all statuses |
| Ergonomic chairs | Very low impressions, serving | No hard blocker confirmed | Review relevance, bid and competition one variable at a time |
| Assembly service | Rejected | Landing page implies unsupported locations | Align geography and destination truth, then resubmit |
| Home-office bundles | Newly serving, 8 hours old | Insufficient observation window | Preserve setup and complete the initial 24-hour check |
Method: freeze campaign settings; capture account, campaign, ad-group and ad statuses; reconcile dates, time zone, billing and allowance; check product and destination eligibility; classify the first confirmed failed gate; change only that gate; and retain screenshots plus timestamps before and after the change.
The audit does not assign “auction loss” merely because no hard blocker is visible. That would be an inference. For a newly launched campaign with no explicit issue, OpenAI recommends allowing at least 24 hours before treating zero delivery as a support case.
Once hard blockers are excluded, create one testable hypothesis at a time:
Do not change ad group structure, hints, image, landing page, bid and budget in one edit. Even if delivery rises, the team will not know which change mattered.
For a real operating example of bounded performance work, see HML's D2C furniture advertising case study. Its outcome is not a ChatGPT Ads benchmark.
Separate platform availability from commercial value.
| Layer | Metric | What it establishes |
|---|---|---|
| Eligibility | Account, campaign, ad and product states | Ability to compete for delivery |
| Delivery | Impressions, reach where available, spend | Exposure occurred |
| Response | Clicks and CTR | Some users engaged with the ad |
| On-site quality | Engaged sessions and funnel events | Post-click behavior |
| Commerce | Finance-verified orders, net revenue and contribution | Attributed business outcome |
| Causality | Holdout or credible matched comparison | Incremental impact |
OpenAI's measurement guide notes that ad clicks can differ from analytics sessions or landing-page visits. Reconcile systems instead of forcing them to match exactly. The attribution glossary explains why recorded credit and causal lift are different questions.
Preserve the smallest useful packet:
Do not send full payment-card details or security codes. OpenAI's help documentation identifies redacted screenshots and precise identifiers as useful support context.
If the account is eligible but delivery diagnosis is being driven by guesses, request a ChatGPT Ads delivery audit. HML's performance marketing service can build the evidence trail, controlled test plan and finance-aligned guardrails before more budget is committed.
Reviewed by rajkumar-tahalani on 27 October 2026. Access dates are shown for time-sensitive references.
AI & Automation
AI Marketing ROI Audit for Indian Small Businesses
AI & Automation
Meta Muse for Small Business: An India Readiness Guide
Free Tool
CAC Calculator
Calculate what it really costs to win a customer.
Case Study
4.5x Total ROI
How a Premium Bespoke Tailoring Brand Achieved 4.5x ROI Across Digital Channels
We help Indian D2C brands grow with performance marketing, AI automation, and AEO-ready content. Book a free strategy call and we'll show you where the biggest wins are.